4 Oct 2026
Performance Indicators of Reliability in Multi-Sport Prediction Models
Performance indicators of reliability in multi-sport prediction models encompass a range of statistical measures that assess how consistently these systems forecast outcomes across diverse athletic disciplines such as football, tennis, and horse racing. Researchers developed these metrics to evaluate model behavior under varying conditions including different data volumes, event frequencies, and environmental factors while analysts track patterns in prediction success rates during periods like October 2026 when seasonal shifts influence multiple sports simultaneously. Data shows that models integrating cross-sport datasets achieve higher calibration scores when they account for sport-specific variables yet maintain unified evaluation frameworks.
Core Metrics for Assessing Prediction Accuracy
Accuracy rates form the foundation of reliability assessments yet experts combine them with precision and recall values to capture a fuller picture of model performance. Studies from the University of Melbourne indicate that multi-sport models often report hit rates between 52 and 68 percent across football matches and tennis sets when calibrated against historical results from 2024 through 2026. Brier scores provide another layer by measuring the mean squared difference between predicted probabilities and actual outcomes and lower values signal stronger reliability particularly when models handle both high-frequency events like horse racing sprints and lower-frequency ones like grand slam tournaments.
Consistency Across Sport-Specific Contexts
Consistency metrics evaluate how well a single model maintains performance levels when applied to different sports without requiring extensive retraining. Observers note that cross-validation techniques reveal stability through metrics such as standard deviation in accuracy across football leagues, tennis surfaces, and racing tracks while those who've examined October 2026 datasets found reduced variance in models that incorporate shared features like player fatigue indicators or track conditions. Reliability indices derived from these measurements help identify systems that avoid overfitting to one sport at the expense of others and figures from the Canadian Sport Institute highlight models achieving consistency scores above 0.75 on normalized scales during multi-month testing periods.
Robustness to Data Variability and External Factors
Robustness indicators measure model resilience when input data changes due to factors such as rule modifications, injury reports, or weather impacts that affect multiple sports at once. Researchers apply stress testing by introducing simulated noise into datasets and tracking resulting shifts in output probabilities with evidence from academic papers published in the Journal of Sports Analytics showing that top-performing multi-sport systems retain over 85 percent of baseline accuracy under moderate perturbations. Calibration plots further illustrate reliability by comparing predicted probabilities against observed frequencies and well-calibrated models produce curves close to the diagonal line across football goal predictions, tennis set wins, and horse racing place finishes.
Turns out that temporal stability serves as an additional indicator because models must perform reliably over extended time frames rather than excelling only during short evaluation windows. Analysts examine rolling window evaluations that span several months and data from October 2026 demonstrates how models incorporating real-time updates maintain lower error rates compared to static versions when tested on concurrent football, tennis, and racing events.
Comparative Benchmarks and Industry Standards
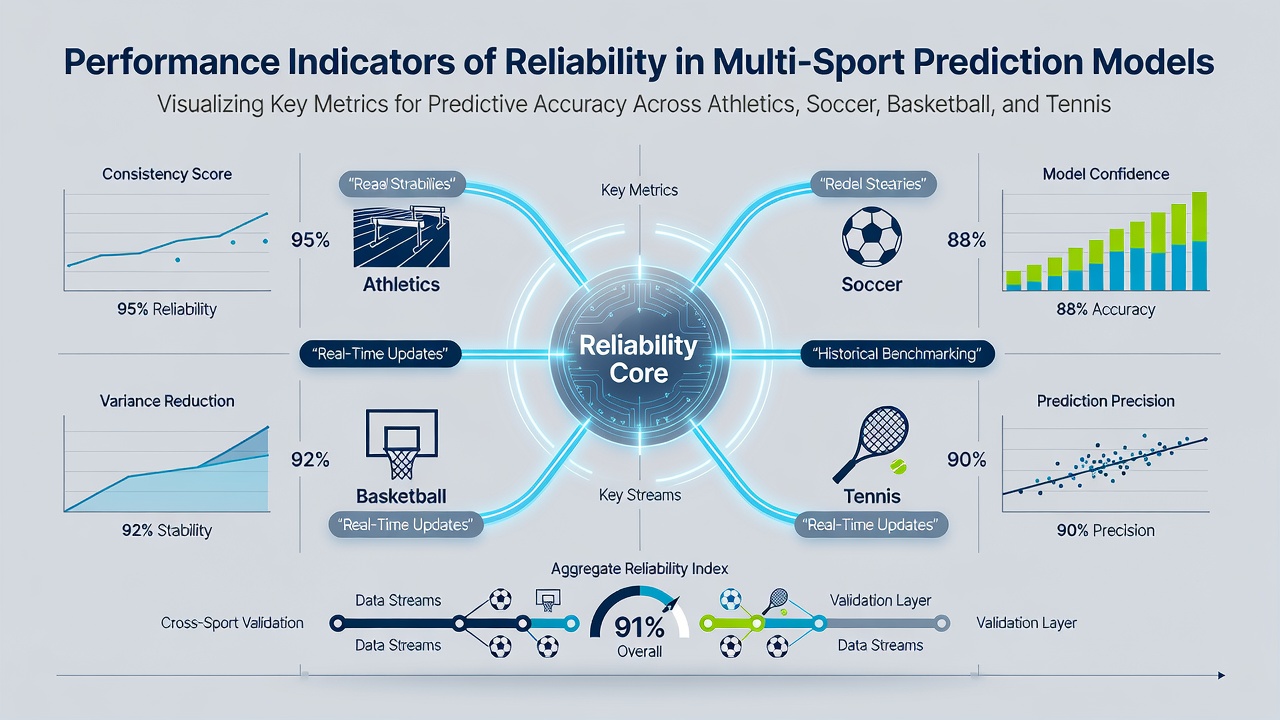
Benchmarking against established standards allows direct comparisons between different multi-sport prediction approaches. Organizations such as the Australian Sports Commission publish reference datasets that enable standardized testing while comparative studies reveal performance gaps between ensemble methods and single-algorithm systems. Those who've studied these benchmarks report that hybrid models combining statistical regression with machine learning components frequently outperform others on aggregate reliability scores across varied sports calendars.
What's significant is the role of information gain metrics that quantify how much predictive value each additional data source contributes when expanding from single-sport to multi-sport frameworks. Evidence suggests these metrics help prioritize inputs like historical head-to-head records or pace ratings that transfer effectively between disciplines and regulatory bodies in the European Union have referenced similar approaches in reports on algorithmic transparency within sports analytics.
Conclusion
Performance indicators of reliability provide structured ways to evaluate multi-sport prediction models through combined accuracy, consistency, robustness, and calibration measures. Data from multiple regions and testing periods including October 2026 underscores the value of unified frameworks that handle sport-specific nuances while delivering stable results across applications. Researchers continue refining these indicators as datasets grow and sports evolve yet the core principles remain focused on measurable, comparable outcomes that support informed use of prediction systems.